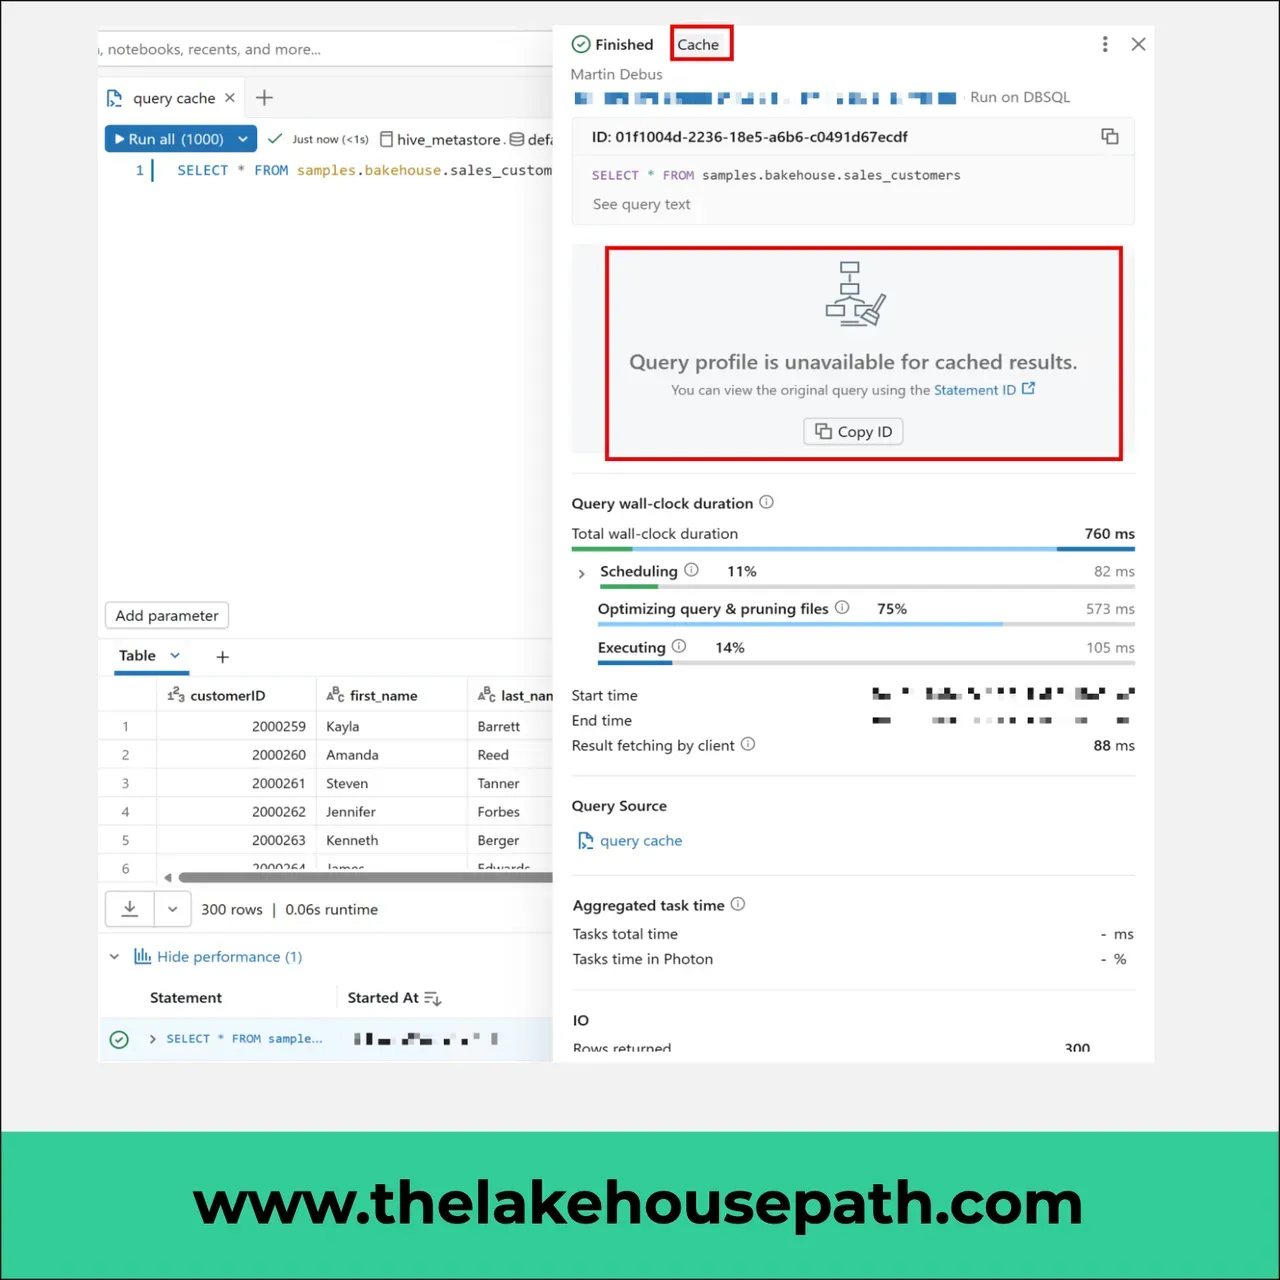

Most data engineers know about Databricks query caching, but few understand how it actually works under the hood.
In my latest blog post, I break down:
- The 4 cache layers (UI, Local, Remote, Disk) and when each kicks in
- How to verify cache usage with system.query.history
- Key differences between Serverless and Classic Warehouses
- Common pitfalls that invalidate your cache One surprising find: Databricks cache is NOT case-sensitive (unlike Snowflake). This means SELECT * FROM table and select * from TABLE will both hit the cache. Small details like this can make a big difference in query performance.
If you’re working with Databricks SQL and want to squeeze more performance out of your queries, check out the full blog post (link is in the comments).