
One of the biggest obstacles in Databricks Delta Live Tables has now been solved.
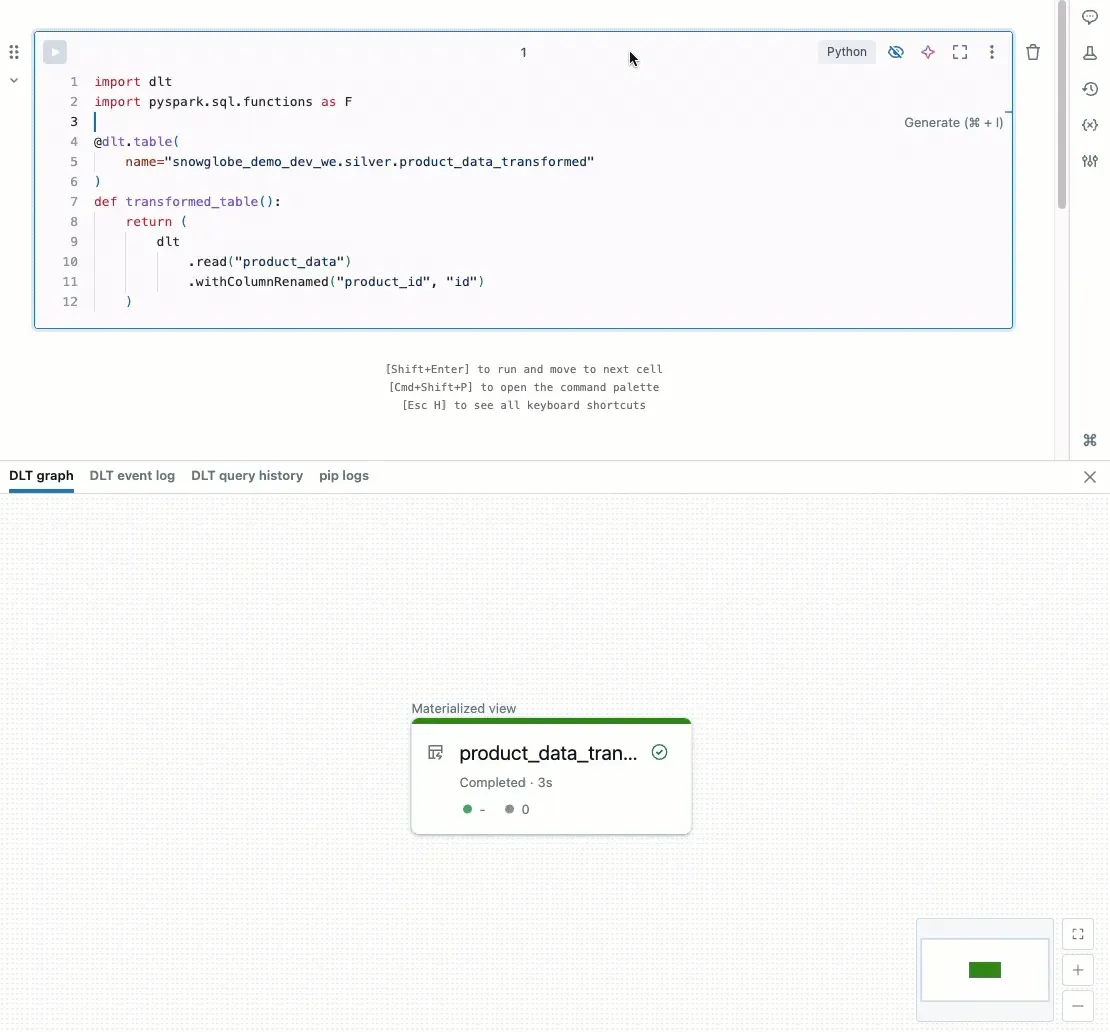
A while back, I built a medallion architecture using Delta Live Tables. While this is an excellent framework, especially for smaller use cases, one thing was particularly frustrating: the target table for a transformation had to be in the same catalog and schema as the source tables. This made it difficult to create a medallion architecture where each layer resides in its own schema within a single DLT job. Instead, I had to manage multiple scattered jobs to achieve this.
Databricks is now rolling out a new feature that allows you to specify the target catalog and schema for your tables directly in your code using the three-tier namespace (catalog, schema, table). Combined with serverless DLT compute, this works seamlessly.
Check it out if you’re using DLT or considering it!
Link to the Azure Databricks documentation is in the comments.