
The _object_metadata column is in public preview (requires Databricks Runtime 18.2 or above).
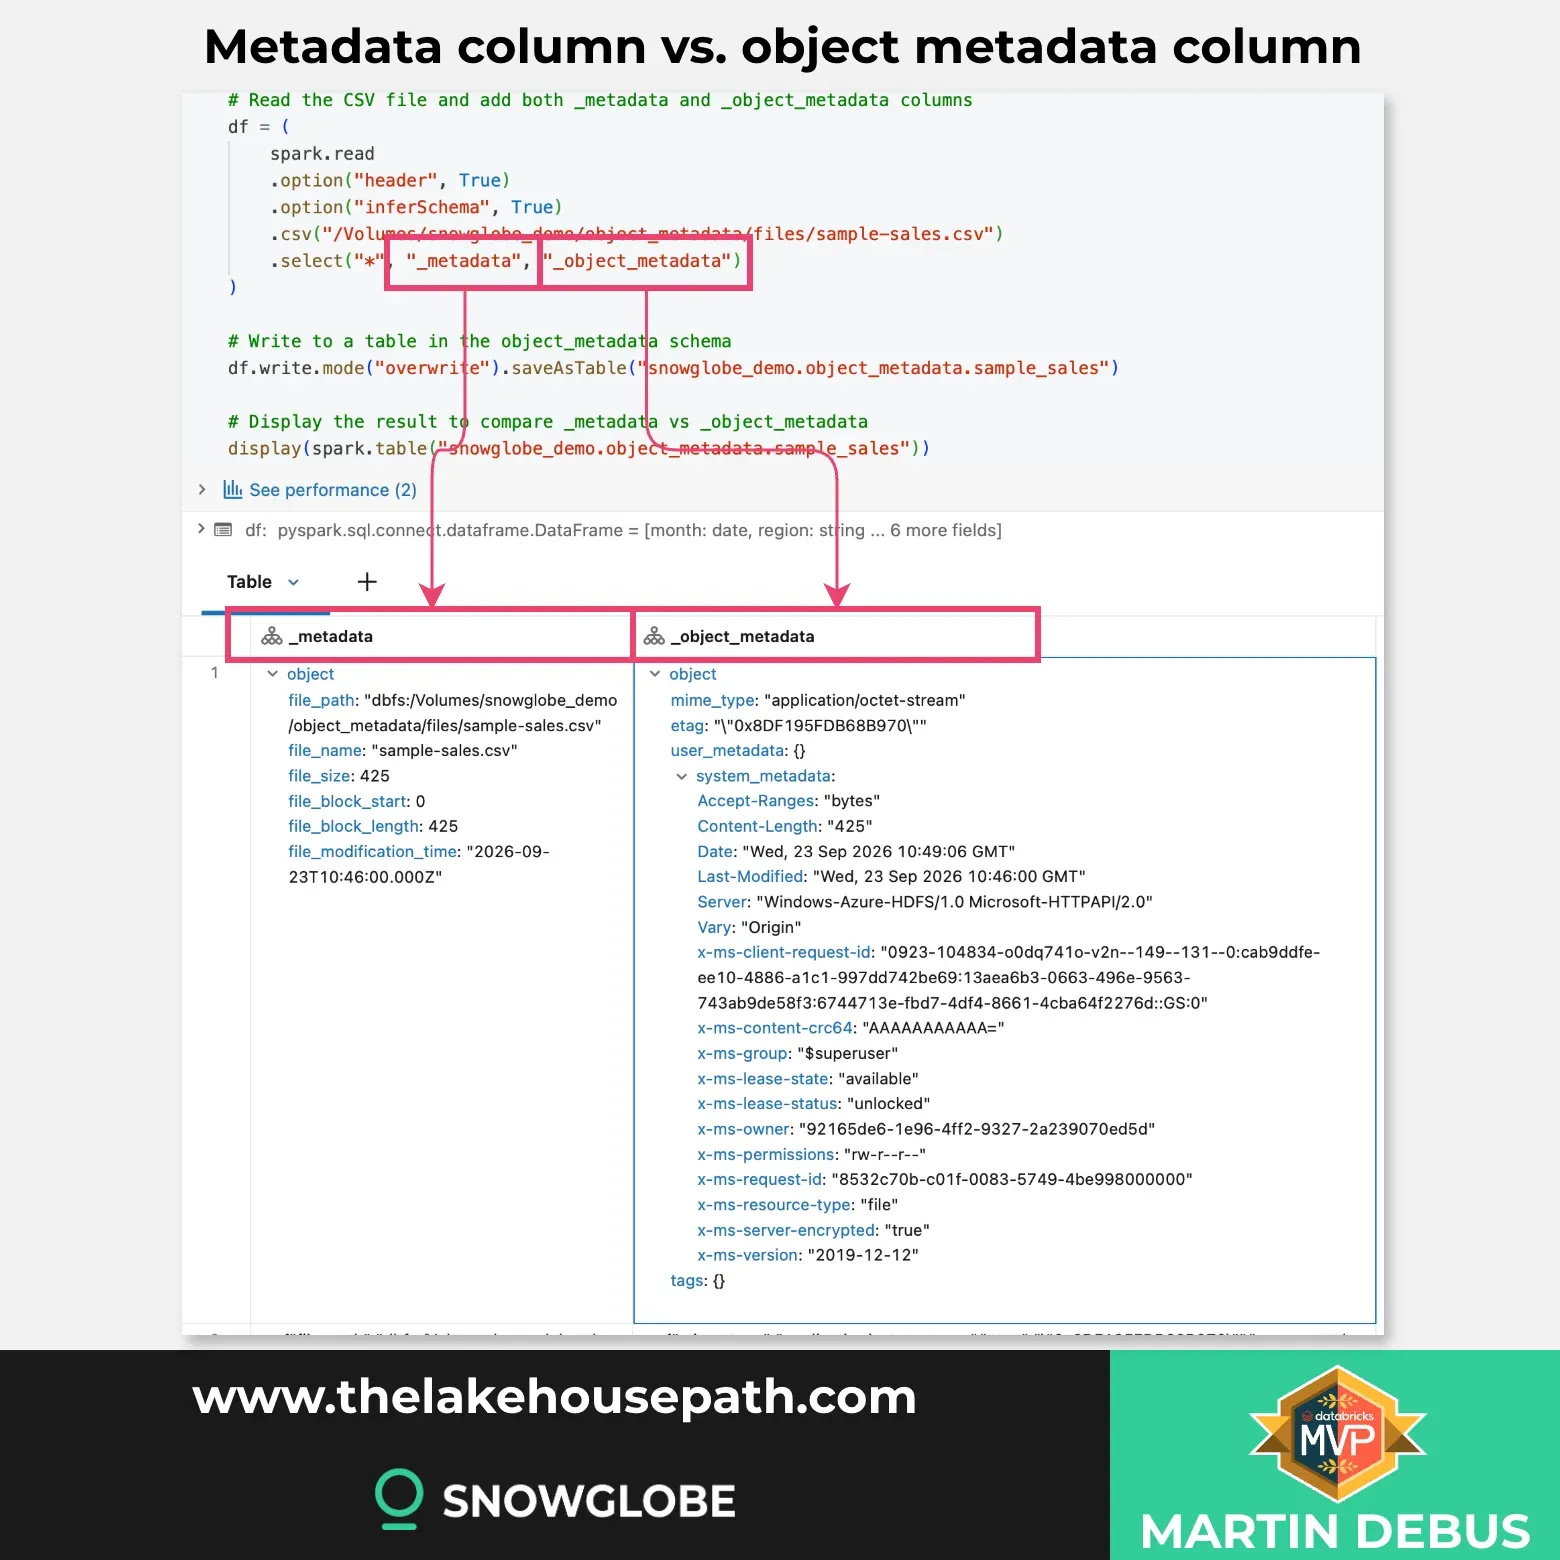
When reading files from cloud storage, you can now add a system column named _object_metadata. This column provides metadata from the cloud object storage, like etags, user metadata, and system metadata.
The basic things like the file path and size are still located in the _metadata column. So _object_metadata provides additional information and is not a richer substitute for _metadata.
One use case that comes to my mind is storing the etag on a bronze table when files are overwritten with the same name and loaded again. This way you can determine which version of the file was read on which row.
Are you using the _object_metadata column yet? What use cases do you see?