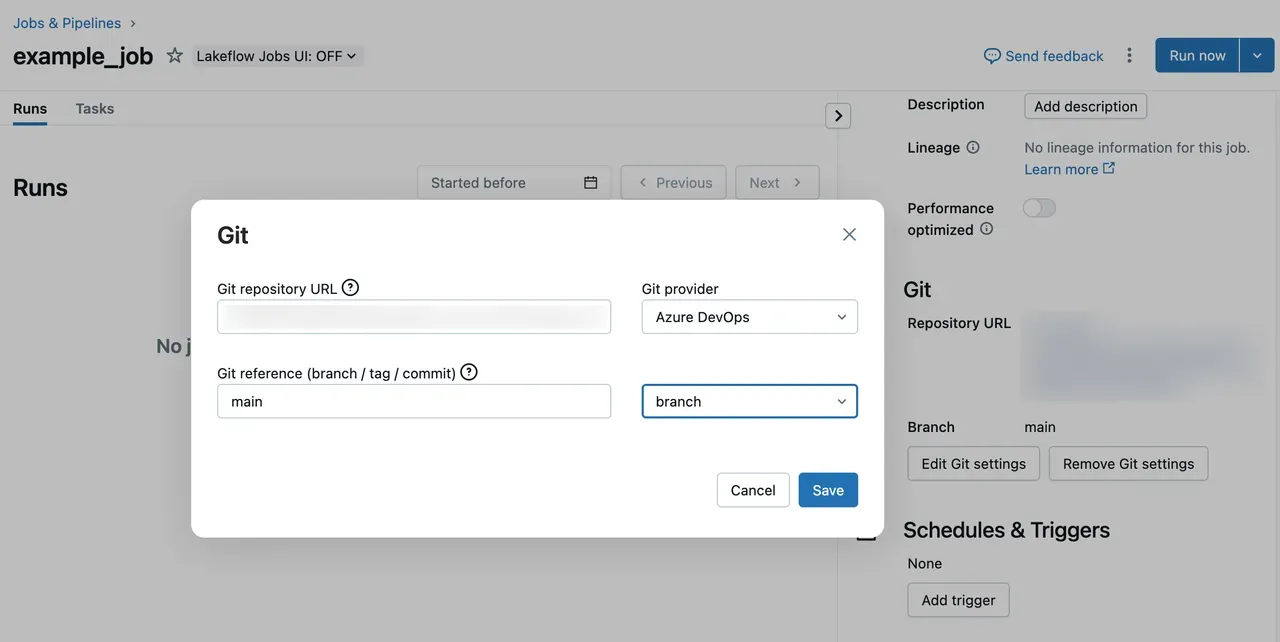

In a Databricks Job Pipeline, you can use Git as source for the code.
This is good practice, because:
- The job does not have rely on the correct code version to be checked out into somewhere in the Workspace.
- You can directly link the Job to a branch, tag or even a specific commit in your repo.
- Databricks does a full checkout of the repo when the job run starts.
How are you managing the code used in jobs?